Relevance is the wrong objective when building AI for environmental crime investigations

A company dumping waste illegally is often untouchable on the statute you would expect. The obvious environmental offence is hard to prove, or the penalty is too small to justify opening a case. But the same company may be exposed somewhere less obvious: a transport regulation, a biocide licensing rule, a reporting obligation buried in an EU directive that nobody on the case team has read. Investigators at the Dutch National Police call this the Al Capone approach – the American state never convicted Capone of the crimes he was known for; it convicted him of tax evasion.
The difficulty is that the ‘“side door”’ is expensive to find. Before a case is formally opened, an investigator writes a pre-assessment document, or “preweegdocument” in Dutch, on whether the case is worth pursuing. Its strength depends on knowing which laws, rulings, and EU instruments might apply, and the most valuable of those are precisely the ones that are not obvious from the facts. That knowledge is spread across separate bodies of text – national law, case law, the memoranda that explain the law, EU legislation, and international eco-jurisprudence. It’s also concentrated in the experience of a small number of people. When they are unavailable, or the angle sits outside their own specialism, it does not get found.
For the past seven months at KickstartAI, we built a retrieval engine for this problem. You upload a pre-assessment document , and the system returns ranked legal angles across the full corpus, including the ones you were not looking for. What follows is a walk through the system end to end. It’s organized around the one design challenge that shaped almost every decision we made, because it runs against the grain of how search engines are normally built: the results our users most needed were, by definition, the results a conventional relevance model would rank last.
What “relevant” means, and why it was the wrong target for environmental crime investigations
Modern retrieval is organized around one objective: return the documents most relevant to the query. Every standard tool serves it. Dense embeddings place semantically similar text nearby. BM25 rewards term overlap. Cross-encoder rerankers re-score each candidate for how well it matches the query, and they are very good at it. The entire stack is a relevance-maximizing machine, and for most search products that is exactly right.
It is wrong here, however. The purpose of this tool is not to retrieve the waste dumping statute for a waste dumping case – the investigator already knows that one. Its value is the biocide licensing angle, the transport rule, the EU filing obligation: results that are, at face value, not obviously relevant to the document you uploaded. A model trained to rank by relevance to the original document will systematically push those to the bottom.
The better it is at its job, the more reliably it buries the results that justify the product’s existence.
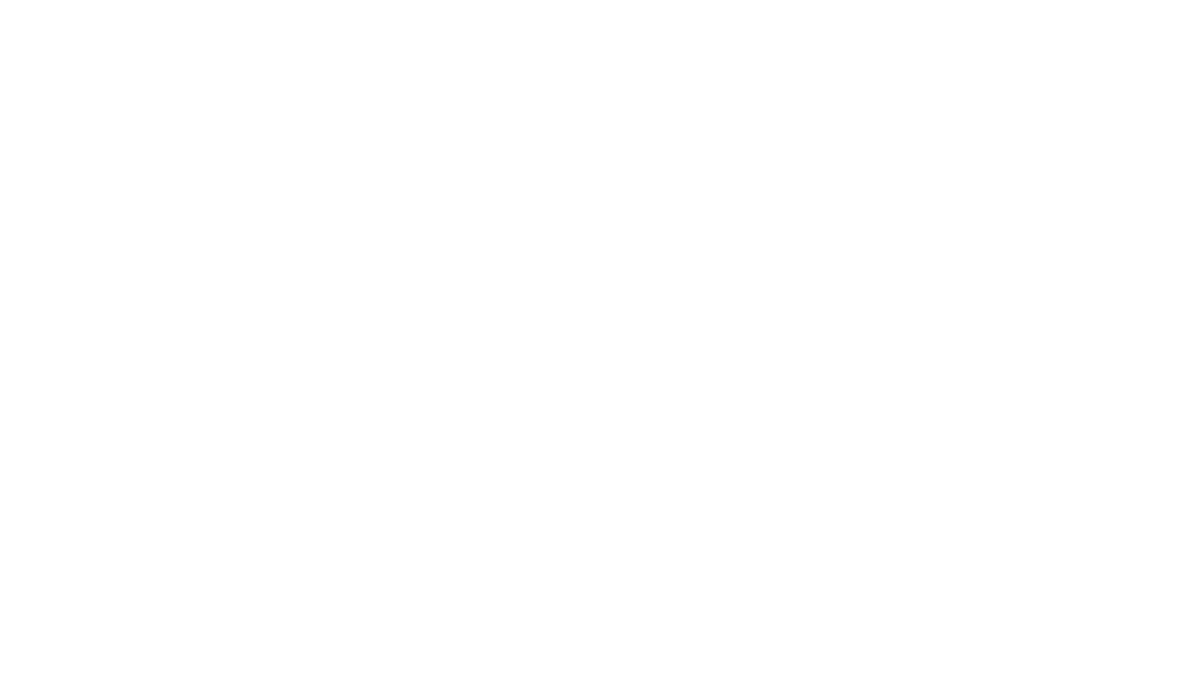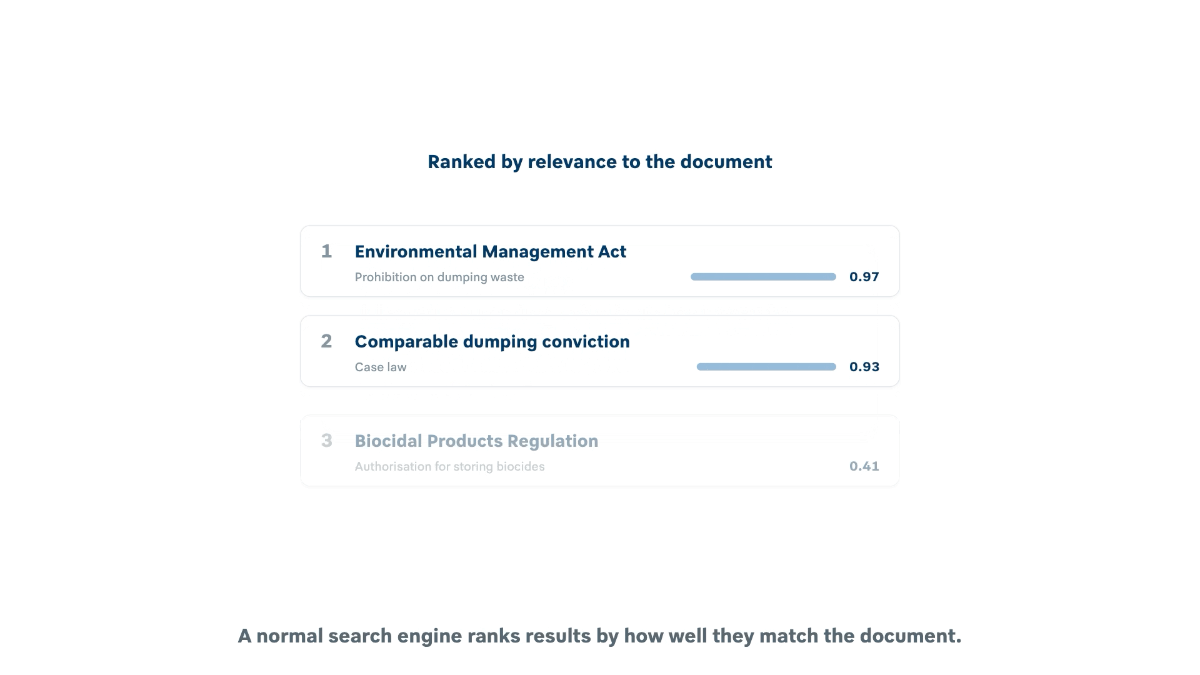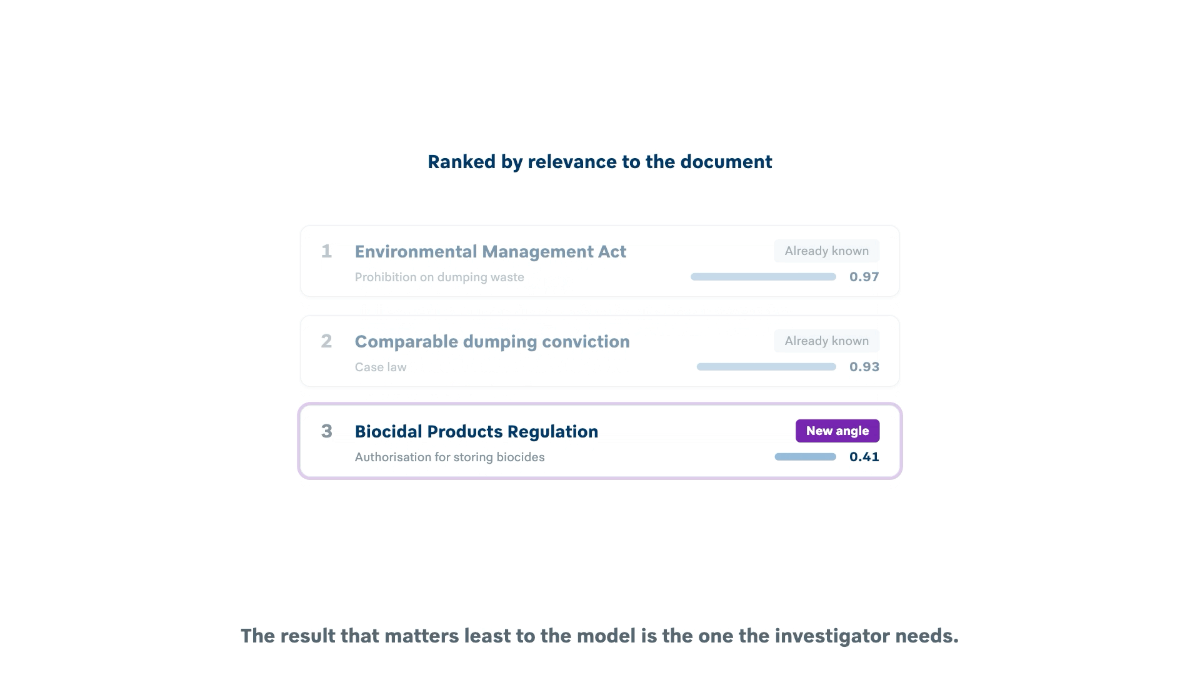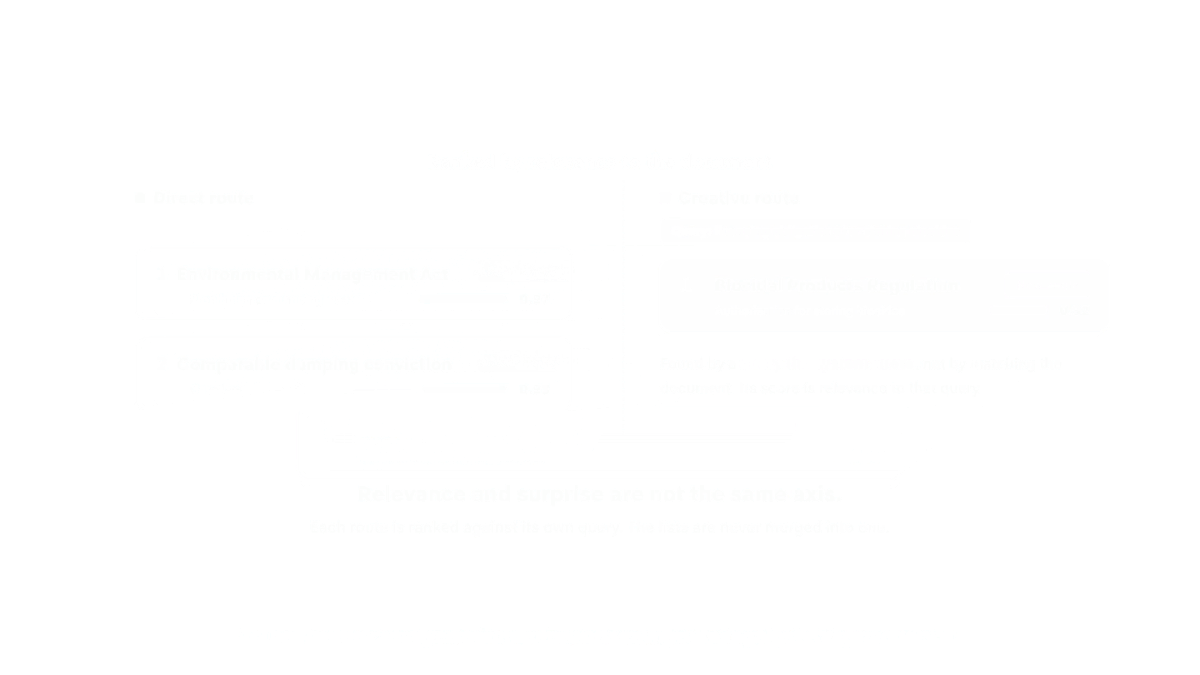
This is not a tuning problem you can fix with a better relevance model. It is a mismatch between the objective the tooling optimizes and the objective the product serves. Recognizing that early – that we were building something whose value was partly surprise, and that surprise and relevance are not the same axis – is what kept us from building a competent search box that solved the wrong problem. None of this means abandoning relevance ranking, however. Every result the system retrieves is still ranked by relevance. What changes is what the results are relevant to, not the uploaded document, but the queries the system writes itself, some of which deliberately leave the document behind.
The system at a glance

The rest of this post follows that pipeline in order, from the corpus through query generation, routes, passage highlights, and the interface, before ending with the evaluation.
Five corpora into one shape
Before any of the retrieval cleverness, most of the work was unglamorous: turning five incompatible bodies of law into something you can search as one. The sources are consolidated Dutch national law (the Basiswettenbestand, structured by article and lid), case law (Rechtspraak, keyed by ECLI), the explanatory memoranda to legislation (Memorie van Toelichting), EU legislation (EUR-Lex, in its own XML), and a corpus of environmental law initiatives such as ecocide (the Eco Jurisprudence Monitor, partly scraped). Each arrives in a different format and cadence. Together, they index to about 69 GB across five search indexes, with case law alone contributing around three million chunks. Normalizing them into one schema and re-chunking to roughly 512 tokens is the bulk of the pipeline.

The interesting piece is how chunk identity works. Every chunk gets a deterministic identifier (a SHA-256 hash of its content and position), created at the first pipeline stage and never re-derived downstream. Because the identifier is a function of the content rather than of when the job ran, re-running the pipeline reproduces exactly the same identifiers. This is what made the corpus maintainable, and when we later needed to backfill metadata, we could rewrite the metadata against stable identifiers without re-embedding anything.
From document to search
At runtime, an uploaded document is read by an LLM into a structured case frame – the roles, the conduct, and the law it can identify – running at a low temperature (0.2), because this is an extraction task and we want it faithful to the document. A second pass turns that case frame into search queries.
How we generate those queries is the part that took three tries. The first version hardcoded query patterns for the domains we had in front of us (biocides, waste, discharges), with regular expressions and hand-written lateral expansions. It demoed beautifully on exactly those cases and would have returned confident nonsense on anything else. The second version dropped the hardcoding and simply chunked the uploaded document, firing each chunk as a query: domain-agnostic, no LLM, and mediocre in a new and more honest way. Only the third version – the LLM case frame above – was good. By then, we had learned not to trust our own judgment about “good”, which is what the evaluation section is about.
Generating the non-obvious queries needs two specific choices. The first is temperature; the creative query pass has a high temperature (0.9), because we are asking the model for range, not fidelity, and the whole point is to leave the neighbourhood of the obvious. The second is a novelty filter. A model with a high temperature will happily regenerate the direct route in different words, which is worse than useless – it spends the creative budget re-finding what another route already covers. So creative queries are filtered against the backbone: any creative query whose wording overlaps a direct query above a threshold is dropped before it ever runs.
Four routes across five indexes
The second pass generates search queries grouped into four routes:
Explicit: statutes named or clearly implied by the document (rule-based, no LLM)
Direct: the legal grounds a specialist would reach for
Lateral: adjacent angles a step removed from the facts
Creative: the Al Capone route, consisting of deliberately non-obvious grounds

Each query is embedded and run as a hybrid search, consisting of BM25 and dense vectors combined per source with reciprocal rank fusion (RRF), spread across the five per-source indexes. A single run generates roughly 36 queries, producing on the order of 1,800 hits that dedupe and merge to around 970 unique chunks. These are streamed into the interface as they arrive and are aggregated by law. The routes are not a presentation detail, but rather the mechanism by which we kept two objectives – find the obvious, find the surprising – from being collapsed into one relevance score that would have served only the first.
Pinpointing the relevant passage
A retrieved chunk is often a whole article of law, consisting of several hundred words, most of them not the reason the result matched. Rather than hand the investigator that wall of text, the interface asks a separate service for the single most relevant sentence in each visible result and underlines it, with the full passage one click away. When a law is relevant for more than one reason, the card lets you page through the passages.

The highlighter runs on its own model, deliberately smaller than the one used for retrieval: ”multilingual-e5-small” (384-dimensional) against ”multilingual-e5-large-instruct” for search. Each chunk’s sentences are embedded once and cached by “mapping_id”, so a repeat highlight is a cosine lookup rather than a new embed. An earlier version ran this on a GPU, but moving it to the small model on CPU made it roughly 60-80x faster on the same hardware and removed the only reason the service needed a GPU at all.
Generating surprise on purpose
The results stream to the browser over server-sent events. Watching queries and hits arrive, grouped by route, turns the wait into a view of the tool thinking. The interface itself was reshaped by a usability review, so the flow became an explicit three-step wizard, including the case picture, the reasoning steps, and the suggestions. Every result also shows which generated query surfaced it. That was the single most-requested feature from our user tests: don’t just show me a result, show me why you are showing it to me.
Built to run self-hosted
Ranking without killing the point
Midway through the project we built the obvious thing: a cross-encoder reranker, re-scoring every result for relevance to the query. It worked, but we deleted it.
A global reranker asks one question of every result: how relevant is this to what you asked? is exactly the question the creative route is designed to fail. Judged against the query, the biocide licensing angle loses to the direct hit every time, by construction. A well-tuned reranker would have converted the tool into an ordinary search box, with cleaner top-of-list metrics, and the product’s reason for existing pushed off the first page.
The rule we settled on is narrow and, we think, general: rerank within a route, never across routes. Ordering inside “direct legal grounds” is a relevance problem, and a reranker is the right tool for it. But the balance between direct and creative is a product decision about how much surprise the user should see, and no relevance model is allowed to make that call, because relevance is the one thing it will always resolve against surprise. The cross-encoder and its tests came out of the live code path and stayed in version history, available if a within-route use ever justifies it.

The transferable learning: if part of your product’s value is non-obvious results, find the place where that value lives and fence it off from your own relevance tooling. Otherwise the tooling, doing its job well, will optimise it away.
Evaluating something whose value is surprise
The uncomfortable consequence of all this is that standard retrieval metrics do not tell you whether the product is good. A metric that rewards relevance to the query rewards the direct route and penalizes the route you built the tool for. So the evaluation had to measure something more difficult, and it had to use the only judges who could: the investigators themselves.
We ran a pooled evaluation in the style of a TREC track. For each test case we pooled the top results, stripped them of the route and query that produced them, and had investigators score each chunk blind – 0 (not relevant), 1 (relevant, but obvious), 2 (creative, new insights) – with the generating query hidden by default and a reveal toggle that was logged, so we could later check whether seeing the query inflated the score. Six investigators scored 382 chunks across their own case types on a single test day, and 381 chunks actually received a score. Of those, 113 scored 0, 239 scored 1, and 29 scored 2 – roughly 30%, 63%, and 8% – for a mean of 0.78.

For a precision search engine that would be a poor result. For an inspiration tool it is close to what you would want. Call it the price of discovery: most results are plausible enough to consider, a minority are dead ends, and a small set is really valuable.
The route breakdown is where the design either justifies itself or does not. The direct route was the safe one: mean 0.88, only 17% scored 0. The creative route was the riskiest by a wide margin (44% of its results scored 0), and at the same time no route earned the top score more often: 9% of its results were marked as creative, matched only by the explicit route and ahead of the safer direct and lateral ones. Creative retrieval is not “worse” than direct retrieval; it is a different bet, one that fails more often and, when it works, works best. A pipeline that had optimized away the 44% would have taken the top-scoring results with them.
Two findings from the same evaluation reinforced the point. First, the source we surfaced most – explanatory memoranda, at 29% of everything shown – was also a leading source of noise, telling us the next relevance win is a filtering problem, not a ranking one. Second, the search engine’s own internal ranking score barely predicted human relevance at all (a Pearson correlation of about 0.2). The system was already not a reliable relevance oracle, which is both a caution about trusting a single score and, read the other way, a reason the fence around the creative route mattered even more than we assumed.
What generalizes
The specific product is narrow, as it’s legal retrieval for a particular investigative workflow at one police unit. The design problem is not. Any system whose value includes showing people something they would not have thought to ask for, sits on the same tension. Its most valuable outputs are the ones a relevance model ranks lowest, and its quality cannot be read off metrics built for relevance.
Three things carried the project through that tension, and we would reach for all three again. Separate the objectives structurally rather than hoping one score can serve both. For us, that was using separate routes. Keep your relevance tooling away from the part of the product that trades in surprise. And evaluate with judges and instruments built for what the product is actually for, because the standard metrics will confidently tell you to delete the reason it exists.
They convicted Al Capone of tax evasion because the direct route was closed. The tool is named after that, and the name turned out to describe how we had to build it as much as what it finds.
Read more about the project: Enhancing environmental crime investigations with AI

